Privacy-first Agentic RAG knowledge assistant
LocalMind answers questions over your documents and the web.
An agent chooses the right tools, hybrid retrieval finds context, and answers include sources.
Weak local matches are blocked by a retrieval score threshold so the system does not sound confident when the docs do not support the answer.
Local inference uses GGUF models via
llama-cpp-python, with hardware detection and optional install of CUDA / Metal / ROCm builds from the Settings UI.
Features
| Feature | Description |
|---|---|
| Agentic routing | Chooses local_rag, web_search, both, or none per query |
| Hybrid retrieval | Dense embeddings + BM25, fused with tunable α |
| Score threshold | Rejects weak local hits → web fallback or refuse |
| Citations | Source chips and retrieved context in the UI |
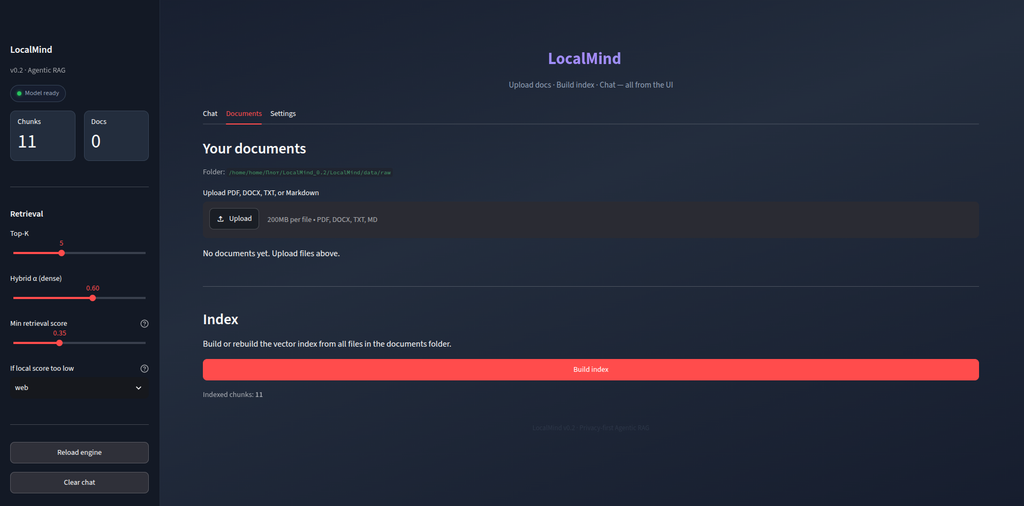
| Document UI | Upload / delete files and Build index in the browser |
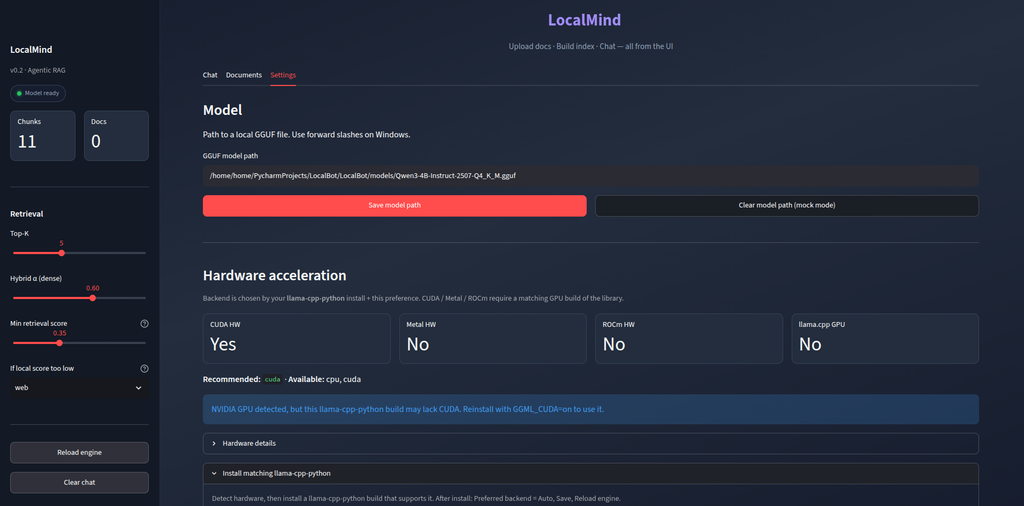
| Settings UI | Model path, GPU backend preference, install GPU llama-cpp-python |
| Hardware acceleration | Detects CUDA, Metal, ROCm; Auto / CPU / custom GPU layers |
| Local GGUF | Inference adapted from LocalBot |
| Easy start | start.bat / start.ps1 / start.sh / python run.py |
Architecture
User query
    │
    ▼
┌─────────────────────┐
│  Agent (router)     │  propose tool
└──────────┬──────────┘
           │
           ▼
    Local hybrid search?
           │
     ┌─────┴─────┐
     │ score OK? │
     └─────┬─────┘
        yes│    no → web fallback or refuse
           ▼
    Context (local and/or web)
           │
           ▼
    Local GGUF LLM
           │
           ▼
    Answer + sources + route metadata
Retrieval score: after local search, if max_score < retrieval_min_score, local chunks are not used for generation.
Project structure
LocalMind/
├── start.bat / start.ps1 / start.sh / run.py   # easy launchers
├── requirements.txt
├── .env                                        # LLM_MODEL_PATH, GPU settings
├── src/
│   ├── config.py
│   ├── llm.py
│   ├── ingestion/          # load, chunk, pipeline
│   ├── retrieval/          # embeddings, Chroma, hybrid search
│   ├── inference/          # GGUF runtime, hardware, backends
│   ├── agent/              # router, tools, score gate
│   ├── services/           # ingest, config, acceleration install
│   └── ui/app.py           # Streamlit UI
├── data/
│   ├── raw/                # your documents
│   ├── processed/          # chunks.jsonl
│   └── vectorstore/        # Chroma DB
├── scripts/ingest.py       # optional CLI ingest
└── docs/                   # architecture, WBS
Quick start
Windows (easiest)
Double-click start.bat
Or in PowerShell:
cd path\to\LocalMind
.\start.ps1
macOS / Linux
chmod +x start.sh
./start.sh
Already in a venv
python run.py
# or
streamlit run src/ui/app.py
The first run of start.bat / start.sh can create .venv and install dependencies.
First-time setup in the UI
-
Settings
- Set GGUF model path (use forward slashes on Windows), e.g.
C:/Users/you/AppData/Roaming/LocalBot/models/your-model.gguf - Save model path
- Set GGUF model path (use forward slashes on Windows), e.g.
-
Hardware acceleration
- Check CUDA / Metal / ROCm detection
- If GPU is present but not used: open Install matching llama-cpp-python, pick the backend, Install
- Preferred backend: Auto, GPU layers: -1, Save, Reload engine
-
Documents
- Upload PDF / DOCX / TXT / MD → Save uploads
- Build index
-
Chat
- Ask questions
- Sidebar: Top-K, hybrid α, min retrieval score, weak-local action (web / refuse)
Configuration
.env (project root)
LLM_MODEL_PATH=C:/path/to/model.gguf
LLM_GPU_LAYERS=-1
LLM_PREFERRED_BACKEND=auto
| Variable | Default | Meaning |
|---|---|---|
LLM_MODEL_PATH | empty | Path to GGUF (empty = mock mode) |
LLM_GPU_LAYERS | -1 | -1 auto, 0 CPU, 1+ fixed layers |
LLM_PREFERRED_BACKEND | auto | auto / cuda / metal / rocm / cpu |
LLM_CONTEXT_SIZE | 4096 | Context window cap |
LLM_TEMPERATURE | 0.1 | Generation temperature |
Also configurable in src/config.py and the UI:
| Setting | Default | Meaning |
|---|---|---|
top_k | 5 | Chunks retrieved |
hybrid_alpha | 0.6 | Dense vs BM25 weight |
retrieval_min_score | 0.35 | Min score to trust local docs |
weak_local_action | web | web fallback or refuse |
UI overview
| Tab | Purpose |
|---|---|
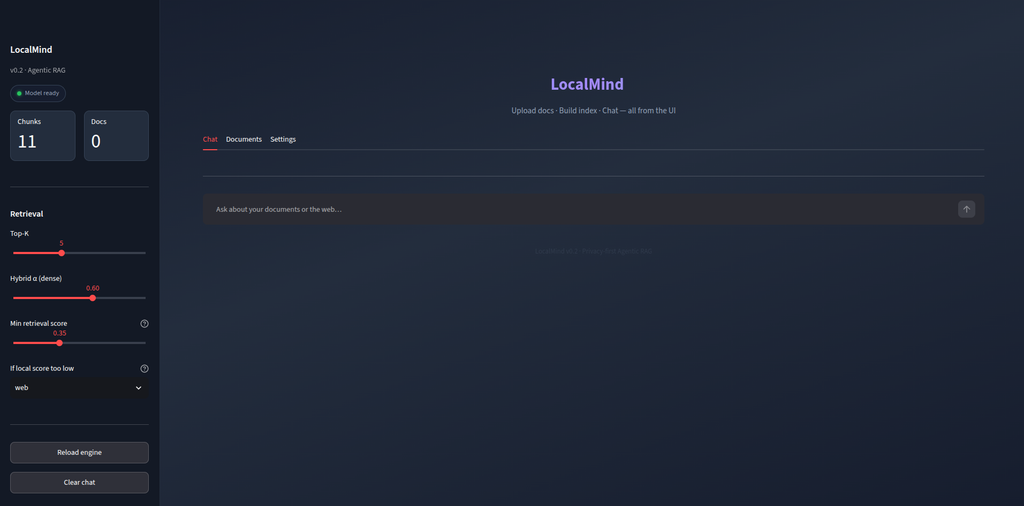
| Chat | Ask questions; see tool badge, scores, overrides, sources |
| Documents | Upload / delete files; build or rebuild the vector index |
| Settings | Model path, hardware status, install GPU llama-cpp-python, acceleration mode |
Sidebar: retrieval controls, min score, weak-local action, reload engine, clear chat.
Tech stack
| Layer | Technology |
|---|---|
| Language | Python 3.10+ |
| UI | Streamlit |
| Embeddings | sentence-transformers |
| Vector DB | Chroma |
| Keyword search | rank-bm25 |
| LLM | llama-cpp-python (GGUF) |
| Web search | DuckDuckGo (ddgs) — no API key |
| Documents | pypdf, python-docx |
| Config | pydantic-settings + .env |
GPU notes
- Detection shows whether NVIDIA / Apple / AMD hardware is present.
-
Inference uses whatever backend your installed
llama-cpp-pythonwas built with. - Use Settings → Install matching llama-cpp-python to install CUDA / Metal / ROCm / CPU builds into the current venv.
- After installing a GPU build: Preferred backend Auto, layers -1, Reload engine.
- If the UI shows GPU hardware but backend stays cpu, the wheel/build likely has no GPU support — reinstall with the matching backend.
Optional CLI ingest
python scripts/ingest.py
Same pipeline as Documents → Build index (reset collection, embed, upsert).
Roadmap
| Item | Status |
|---|---|
| Ingestion + hybrid RAG + agent | Done |
| Score threshold + web/refuse | Done |
| UI: chat, docs, settings | Done |
| Hardware detect + GPU install helper | Done |
| One-click start scripts | Done |
| Golden evaluation set + metrics | Planned |
| Streaming answers | Planned |
| FastAPI API layer | Planned |
| Reranker | Planned |
Related project
LocalBot — private desktop AI assistant (local GGUF, hardware-aware loading, web search, documents).
LocalMind reuses that inference approach inside a focused Agentic RAG system.