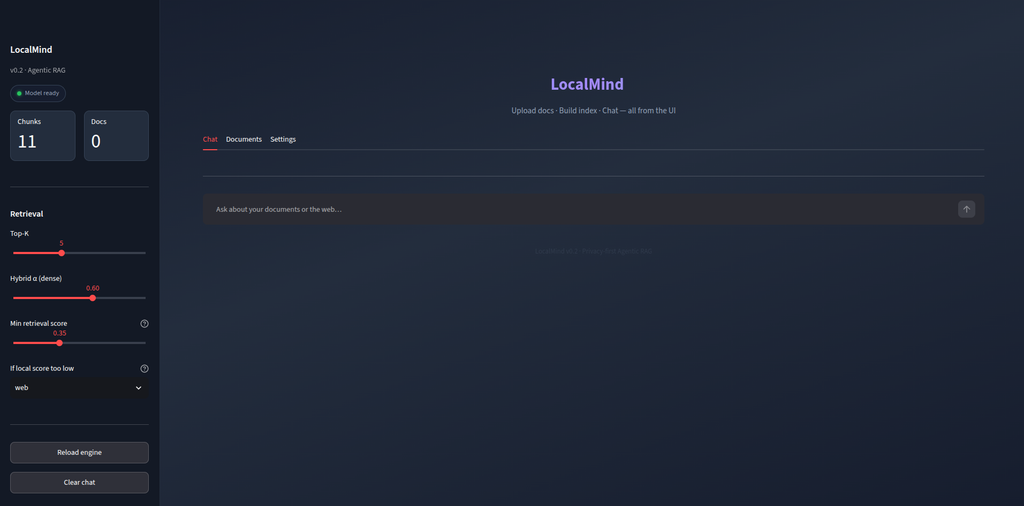
I shipped a solid round of updates to LocalMind, my privacy-first Agentic RAG assistant. The goal was simple: less terminal friction, clearer retrieval behavior, and hardware acceleration that you can actually turn on from the app.
From “run three commands” to open and go
Starting the app used to mean activating a venv and remembering a Streamlit path. Now you can:
- Double-click start.bat on Windows
- Or run start.ps1 / start.sh / python run.py
The launcher can create the venv and install dependencies on first run. That sounds small, but it changes who can try the project.
Everything important is in the UI
LocalMind is no longer “edit files, then chat.”
Documents
Upload PDF, DOCX, TXT, or Markdown, delete files, and Build index in one place. No separate ingest step required for normal use.
Settings
- GGUF model path (saved to .env)
- Preferred backend: Auto / CUDA / Metal / ROCm / CPU
- GPU layers (−1 auto, 0 CPU, or fixed)
- Status for what is actually loaded
Chat
Same agentic flow, with tool badges, sources, and more visible routing decisions.
The important RAG fix: retrieval must earn generation
A common failure mode in agentic RAG: the router picks local docs, retrieval returns weak chunks, and the model still answers with confidence.
LocalMind now applies a retrieval score threshold after hybrid search (dense + BM25):
- If max_score is below the threshold → local context is rejected
- Then either fall back to web search or refuse (configurable in the sidebar)
Under each answer you can see proposed tool, max local score, and whether the route was overridden. Soft “please don’t hallucinate” prompts are not enough; this is a hard gate.
Hardware acceleration you can install from Settings
Detecting a GPU is not the same as using one. Inference depends on how llama-cpp-python was built.
Settings now:
- Detects CUDA, Metal, and ROCm hardware
- Offers Install matching llama-cpp-python for that backend
- Prefer prebuilt CUDA wheels when possible, with source builds for Metal / ROCm / fallback
After install: set backend to Auto, GPU layers to -1, reload the engine.
What this is for
LocalMind is still a focused demo of production-shaped GenAI work:
- RAG + hybrid retrieval
- Agents with tool routing
- Evaluation-minded design (thresholds, visible overrides)
- Local inference with a path to real GPU use
- Clear project structure and a UI that stakeholders can actually try
Next up: a proper golden evaluation set and metrics. A threshold is only as good as the numbers behind it.
GitHub: LocalMind · related: LocalBot
Leave a Reply